Case study · Public interest / open government data and AI agents
Government open data that an AI agent can find, query and cite without a human in the loop
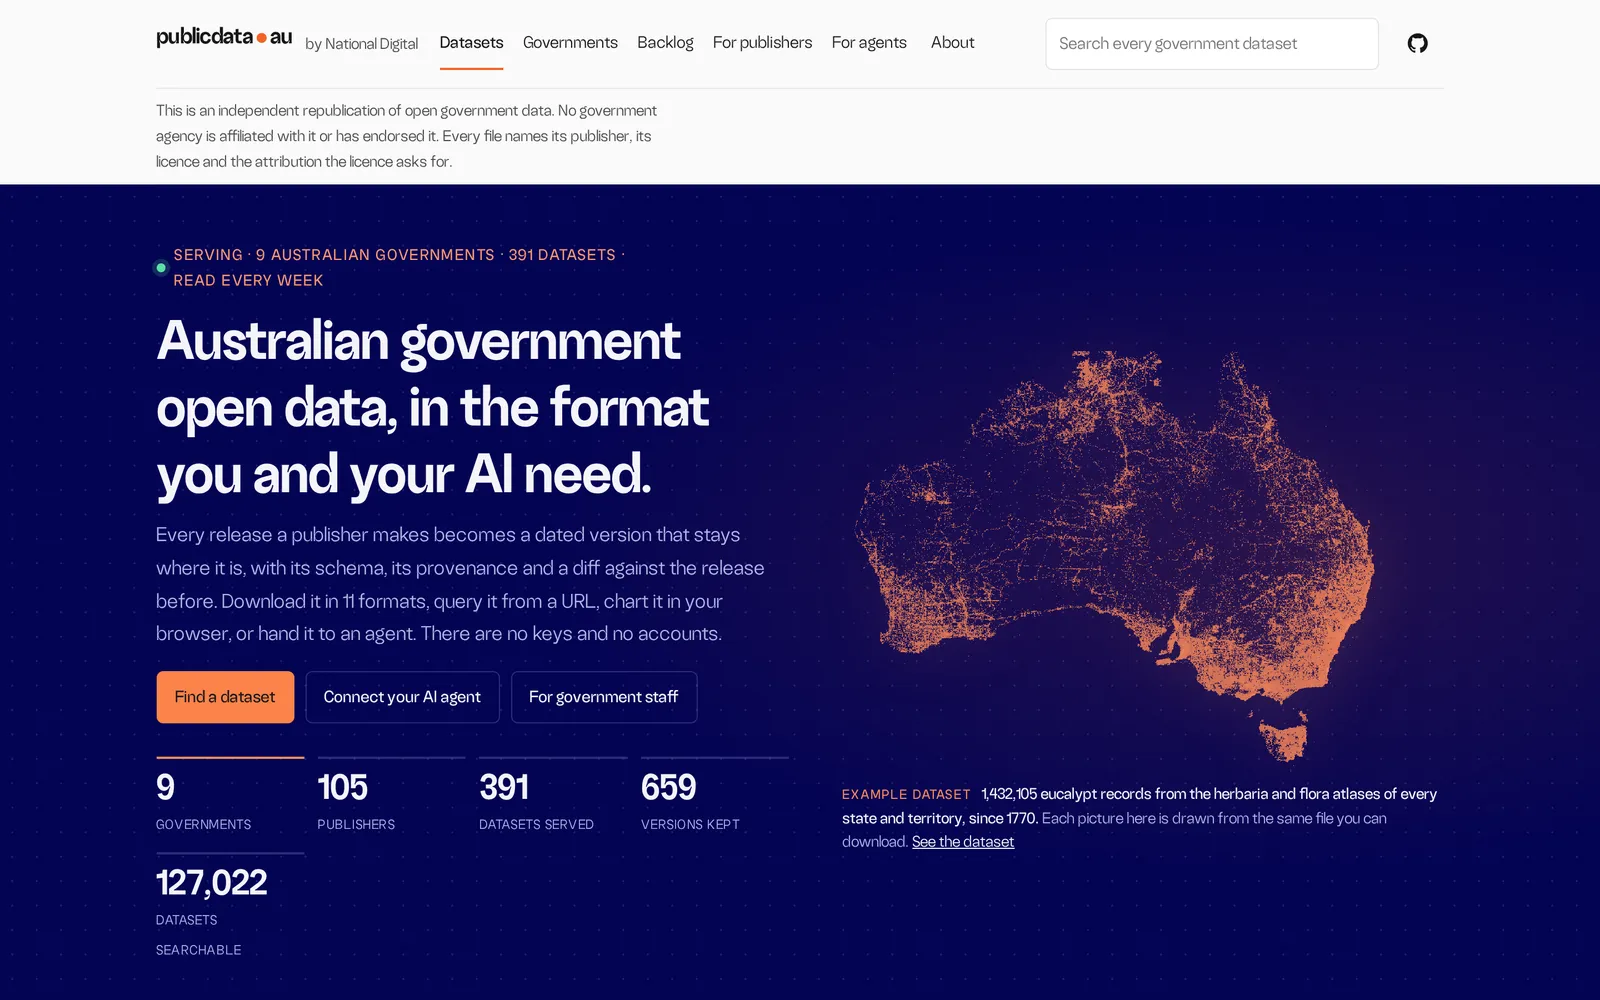
publicdata.au is a National Digital product that republishes Australian government open data as dated versions and serves it to AI agents through a registered MCP server.
National Digital builds MCP servers and AI agent tools like the one behind publicdata.au.
Last updated

At a glance
- Industry
- Public interest / open government data and AI agents
- Engagement type
- In-house product
- First release
- 2026
- Team
- National Digital engineering team
✓ Verified Review
“Most government sources publish their data as a CSV drop and leave it there. The Commonwealth's own data policy says that data should be machine-readable, available through an API and kept up to date automatically, so it can improve services and grow the economy. We built publicdata.au to do that work, so the engineers and AI agents building applications for citizens can use the data the way it was released to be used.”
Cameron Young CEO at National Digital
publicdata.au by the numbers
12
Tools on the MCP server
10
Tools registered in the browser through WebMCP
391
Datasets live at the 29 October 2026 build
169,597,428
Rows an agent can filter and aggregate at that build
The challenge
The Australian Government's Public Data Policy Statement commits agencies to publish data that is machine-readable, with API access, and kept up to date in an automated way. Most government data is still published as a CSV or Excel drop on a portal, with columns renamed between releases and files replaced in place. An engineer building an application for citizens, or an AI agent answering a question for one, has to find, parse and clean the file before any real work starts.
What we built
One pipeline that keeps every release and builds the files, the query API and the agent tools from the same model. Agents get a remote MCP server and in-browser WebMCP tools with identical definitions, and every answer carries its version, licence and attribution. A licence gate holds any dataset whose licence cannot be confirmed.
- A remote MCP server at /mcp, listed in the official MCP Registry and installable in Claude, VS Code and Cursor
- The same tools registered in the browser through WebMCP, defaulting to the dataset on the page and describing its fields
- One definition of every tool and API parameter, generated into both surfaces and held to them by a gate and parity tests
- Discovery files for agents: llms.txt, an Agentic Resource Discovery manifest, an MCP server card and a Markdown twin of every page
- A licence gate that holds any dataset whose licence it cannot confirm and states the reason on the backlog page
- Immutable dated versions, each with a manifest, the publisher's own file and a row-level diff
What we built in each area
Data & reporting
One pipeline keeps every release and builds every file format from the same model, with Parquet as the base format. Raw files are stored by content hash.
- Python
- DuckDB
- Parquet
- Cloudflare R2
AI & automation
Agents use a remote MCP server on Cloudflare Pages Functions, and the same tools are registered in the browser through WebMCP.
- Model Context Protocol
- WebMCP
- Cloudflare Pages
Integration layer
A query API over Cloudflare D1 is described by OpenAPI. Its text is written once and generated into both the API and the agent tools.
- OpenAPI
- Cloudflare D1
The outcome
At its build of 29 October 2026 the site served 391 datasets and 169,597,428 rows. All of it is reachable through the MCP server and the in-browser tools. The MCP server is active in the official MCP Registry as au.publicdata/mcp, and each release republishes the registry entry only when what a client sees has changed. Each queryable dataset is also an MCP resource listing its fields, their types, the publisher's descriptions and the values they hold, so an agent can read a dataset's shape before it writes a query.
Where it went next
Agents can vote for the next dataset through the same tools people use, and the votes decide what is built next. Every version is kept, and its raw bytes and manifests sit in both versioned object storage and git, so an answer an agent cited against a dated version can be rebuilt from either copy.
This case study describes a live product designed and built by National Digital. Counts are read from the live site's build of 29 October 2026 and from its MCP server on 31 October 2026. The site is independent, and no government agency runs it, funds it or has endorsed it.
Key Takeaways
Engineering open data for AI agents
- Agents get first-class tools: a registered MCP server and WebMCP on every page.Critical
The remote MCP server needs no key or account and is listed in the official MCP Registry. In a browser that exposes WebMCP, the same tools register on each page and default to the dataset shown, so an agent can answer a question about the data it is reading.
- Each tool is defined once, so the two surfaces cannot drift apart.Critical
Every tool, parameter and limit lives in one api.json file that the build writes into the MCP server, the page scripts, OpenAPI and llms.txt. A gate fails the deploy if a copy drifts, and a test runs each tool through both surfaces and requires identical answers.
- Every answer is citable, because it names its version and carries the publisher's attribution.Critical
Tool answers include the version, the licence, the attribution string and the query URL, and the server instructions tell agents to show all three. A dated version always returns the same bytes, so a figure an agent cites can still be checked years later.
- Agents read a dataset's shape before they query it.Important
Each queryable dataset is an MCP resource listing its fields, their types, the publisher's descriptions, their ranges and the values of small fields. On a dataset page the WebMCP tools carry the same detail, so an agent sees the exact values a filter needs.
- The licence is read on every run and gates the publish.Important
CC BY and CC0 data publishes with the attribution in the publisher's own words. A licence the agency has not specified is held until a person records evidence, and a no-derivatives licence is never published. Old versions stay up under the licence they were published under.
National Digital built publicdata.au and runs it as its own product. It serves Australian government open data to AI agents through a registered MCP server and WebMCP tools defined once and tested for parity, and every answer names its version.
Questions about publicdata.au and its MCP server
How does publicdata.au serve data to AI agents through an MCP server?
An agent connects to the remote MCP server at publicdata.au/mcp, which needs no key and is listed in the official MCP Registry. The server is stateless and runs as a Cloudflare Pages Function over Streamable HTTP. Its 12 tools search datasets, read fields, query and count rows across the whole table, compare versions and vote for new data. Claude, VS Code and Cursor can connect to it.
What is WebMCP on publicdata.au, and how does it differ from the MCP server?
WebMCP lets a page register tools that an AI agent in the browser can call. publicdata.au registers 10 of the data tools on every page through navigator.modelContext, and on a dataset page they default to that dataset and describe its fields in the publisher's wording. The tool definitions come from the same file as the MCP server's, so both surfaces give the same answers.
Can an agent cite what it finds on publicdata.au?
Yes. Every tool answer names the version it came from and carries the licence, the publisher's attribution string and the query URL, and the server tells agents to show them. Every data file carries a cite string in its header. A dated version URL always returns the same bytes, so a figure an agent quotes today can be checked against the same data years from now.
What stack does publicdata.au run on?
A Python build keeps each release in Parquet and writes the other formats from it, including a DuckDB database. Cloudflare Pages serves the site and the MCP server, D1 answers the query API, and R2 holds the publisher's bytes by hash. The tools and the API are described once in api.json and published as an MCP server, WebMCP tools and an OpenAPI description.
How much data does publicdata.au serve?
At its build of 29 October 2026 the site served 391 datasets and 169,597,428 rows, and it keeps every version a publisher releases. The count is read from the site's health report, so it grows as new datasets are added. Datasets that are not built yet appear in a backlog that people and agents can vote on.
Why do governments release open data, and what does publicdata.au add?
The Australian Government Public Data Policy Statement calls government data a strategic national resource and commits agencies to machine-readable data with API access. A CSV drop leaves part of that undone. publicdata.au turns each release into a typed, versioned dataset with a query API and an MCP server.
How does publicdata.au handle licences?
The licence is read on every run and decides whether the dataset can be published. CC BY and CC0 data is published with the publisher's own attribution wording. A licence left as 'specified by agency' is held until a person records evidence of what it permits, and a no-derivatives licence is never published. The backlog page states the reason for each dataset that is held.
Is publicdata.au an official government site?
It is independent. National Digital runs it, and no government agency runs it, funds it or has endorsed it. Every page and every data payload says so, and a build gate fails the deploy if a payload is missing that statement, its attribution or its source hash.
More of our own products
What's next
Want AI agents to use your data correctly?
On publicdata.au, agents get an MCP server and in-browser tools that answer from versioned data and cite their source. If your organisation publishes data or services that agents will act on, see how we approach AI agents and MCP servers, platform engineering and data analysis and insight platforms.
Want an MCP server or agent tools for your own data?
Tell us what you're building. We'll come back within one business day with what we'd do first and what it would take.